Skip to content

Blog

Genotype Readers in Python: BCF, PGEN, and BGEN at One Thread

Reader benchmarks are easy to overstate: one tool counts records while another materializes genotypes, or a parallel result is placed next to a serial one. Here every headline result uses one thread and produces the same dense matrix, with the same row order, sample order, dtype, and missing-value convention.

The result is mixed, and more useful for it. polars-bio is fastest on the BCF and PGEN workloads. On BGEN dosage, the independent bgen package is 3.9% faster at one thread; polars-bio is 1.54× faster than snputils. polars-bio has zero mismatches against the independent oracle in every workload tested.

Cheap to rewrite, expensive to get right: the "FastQC-compatible" trap

A wave of AI-assisted rewrites is coming to bioinformatics. Decades-old tools written in Perl, Java, and C are being reimplemented in Rust and Go, often by an LLM in an afternoon. The rewrites.bio manifesto puts it well: "The question is not whether it will happen, but whether it will happen well." Because — and this is the whole point — cheap code is not the same as correct code.

Here is the thesis of this post: in the age of cheap AI-assisted rewrites, writing the code is no longer the hard part. The hard, still-valuable part is the engineering judgment around it — sound architecture, verified quality, and the discipline of spec- (SDD) and test-driven development (TDD) — plus the honesty to report what you actually built. A rewrite is not a translation to a new language; it is a validation contract. We recently shipped a streaming FastQC in polars-bio, and along the way benchmarked RastQC, a Rust reimplementation of FastQC. RastQC turns out to be a clean worked example of what happens when a rewrite skips those principles.

Streaming FastQC in polars-bio: compatible and scalable

FastQC is the de-facto first look at any sequencing run — but it is a single-threaded Java tool, and the fast Rust reimplementations tend to trade away correctness. polars-bio now runs the full FastQC module suite as a single streaming pass over FASTQ, computed on Apache DataFusion: FastQC 0.12.1-compatible under explicit parity checks (bit-exact for deterministic/count modules, tolerance-checked for floating metrics), and a fraction of the time and memory.

Benchmarking DataFrame Paths in polars-bio 0.29.0

polars-bio 0.29.0 adds support for Pandas >= 3.0.0. Since pandas 3.0 made PyArrow-backed data even more central, with the new default string dtype using pyarrow under the hood when available, we wanted to measure what that means for interval workloads in practice.

So instead of comparing different interval libraries, this benchmark compares different input and execution paths through the same polars-bio range engine:

  • direct Parquet scan through Apache DataFusion
  • Pandas DataFrame
  • Pandas with Arrow-backed dtypes
  • Polars eager DataFrame
  • Polars lazy LazyFrame

The question is simple: how much overhead do you pay once data is materialized into a Python DataFrame, and how much of that gap can Arrow-backed Pandas close?

Interval operations benchmark — update February 2026

Introduction

Back in September 2025 we benchmarked three libraries across three operations. A lot has changed since then. In December 2025, pyranges1 published a preprint describing its Rust-powered backend (ruranges) and an expanded set of interval operations. On the polars-bio side, version 0.24.0 ships a fully rewritten range-operations engine built on upstream DataFusion UDTF providers (OverlapProvider, NearestProvider, and the new coverage/cluster/complement/merge/subtract providers from datafusion-bio-function-ranges), replacing the earlier sequila-native backend.

Benchmarking Genomic Format Readers in Python with Polars

Genomic analyses in Python typically start with reading BAM, VCF, or FASTQ files into memory. The choice of library for this step can have a dramatic impact on both wall-clock time and memory consumption — especially as datasets grow to tens or hundreds of millions of records.

pysam has long been the go-to Python library for working with these formats. It provides comprehensive bindings to htslib and is battle-tested across thousands of projects. However, several newer libraries have emerged that leverage Apache Arrow columnar format and Rust-based parsers to offer potentially better performance.

In this post, we benchmark four Python libraries head-to-head on real-world genomic data to find out which offers the best combination of speed and memory efficiency for reading BAM, VCF, and FASTQ files.

GFF File Reading Performance Enhancements in polars-bio 0.15.0

We're excited to announce significant performance improvements to GFF file reading in polars-bio 0.15.0. This release introduces two major optimizations that dramatically improve both speed and memory efficiency when working with GFF files:

Key Enhancements

Projection Pushdown: Only the columns you need are read from disk, reducing I/O overhead and memory usage. This is particularly beneficial when working with wide GFF files that contain many optional attributes.

Predicate Pushdown: Row filtering is applied during the file reading process, eliminating the need to load irrelevant data into memory. This allows for lightning-fast queries on large GFF datasets.

Fully Streamed Parallel Reads: BGZF-compressed files can now be read in parallel with true streaming, enabling out-of-core processing of massive genomic datasets without memory constraints.

Benchmark Methodology

To evaluate these improvements, we conducted comprehensive benchmarks comparing three popular data processing libraries:

  • Pandas: The traditional Python data analysis library
  • Polars: High-performance DataFrame library with lazy evaluation
  • polars-bio: Our specialized genomic data processing library built on Polars and Apache DataFusion

All benchmarks were performed on a large GFF file (~7.7 million records, file and index needed for parallel reading) with both full scan and filtered query scenarios to demonstrate real-world performance gains.

For pandas and polars reading, we used the following methods (thanks to @urineri for the Polars code). Since Polars decompresses compressed CSV/TSV files completely in memory as highlighted here, we also used polars_streaming_csv_decompression, a great plugin developed by @ghuls to enable streaming decompression in Polars.

Test query used for filtered benchmarks (Polars and polars-bio):

 result = (
        lf.filter(
            (pl.col("seqid") == "chrY")
            & (pl.col("start") < 500000)
            & (pl.col("end") > 510000)
        )
        .select(["seqid", "start", "end", "type"])
        .collect()
    )

The above query is very selective and returns only two rows from the entire dataset.

Results

Complete benchmark code and results are available in the polars-bio repository.
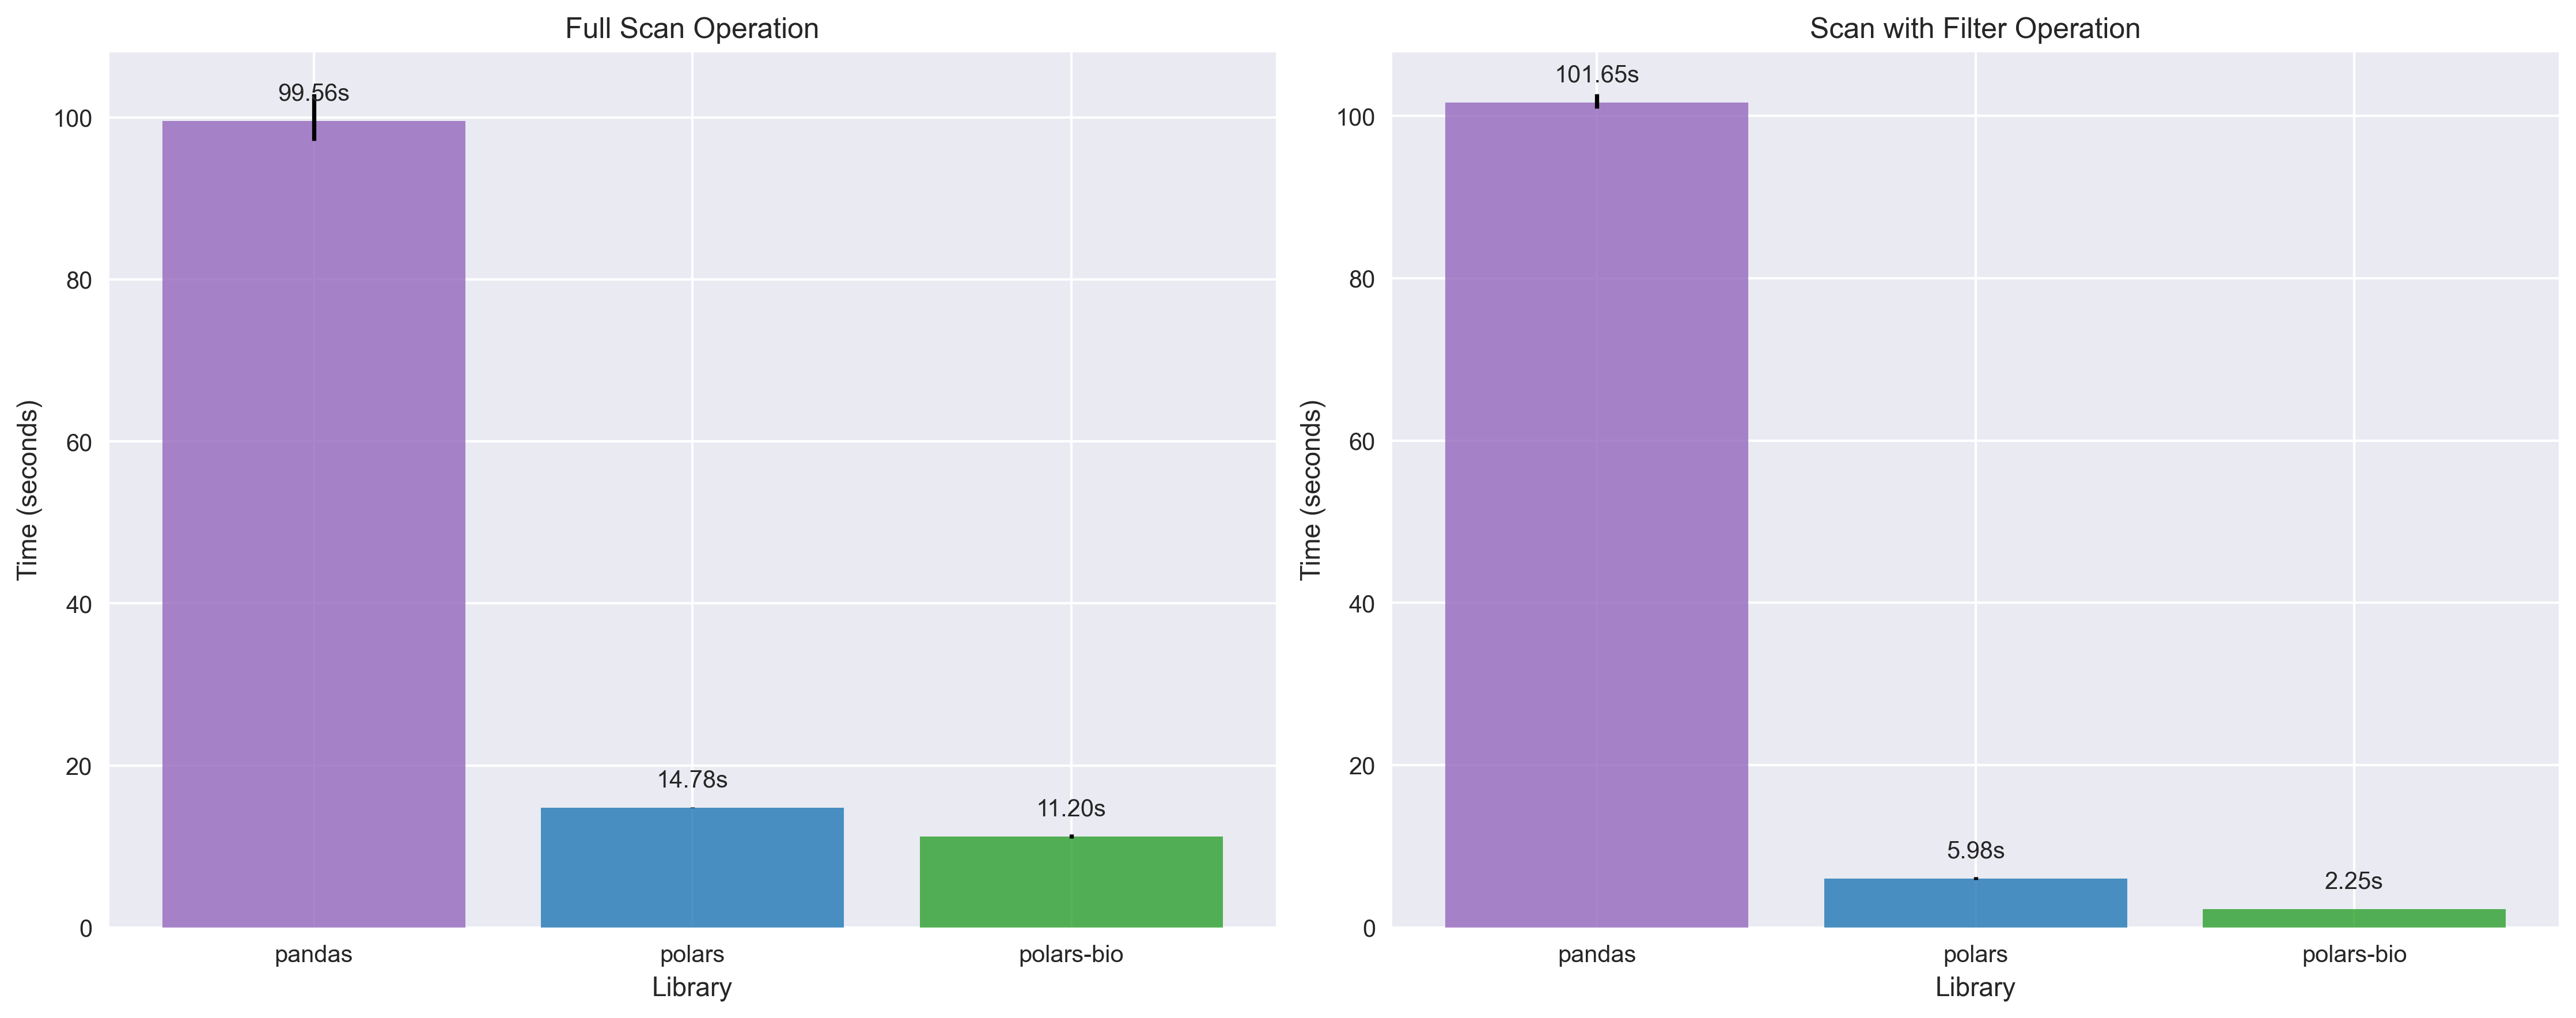
Single-threaded performance

general_performance.png

Key takeaways:

  • polars-bio delivers comparable performance to standard Polars for full scan operations and both significantly outperform Pandas.
  • In the case of filtered queries, we can see further performance improvements with Polars and polars-bio thanks to predicate and projection pushdown optimizations. polars-bio is 2.5x faster than standard Polars.
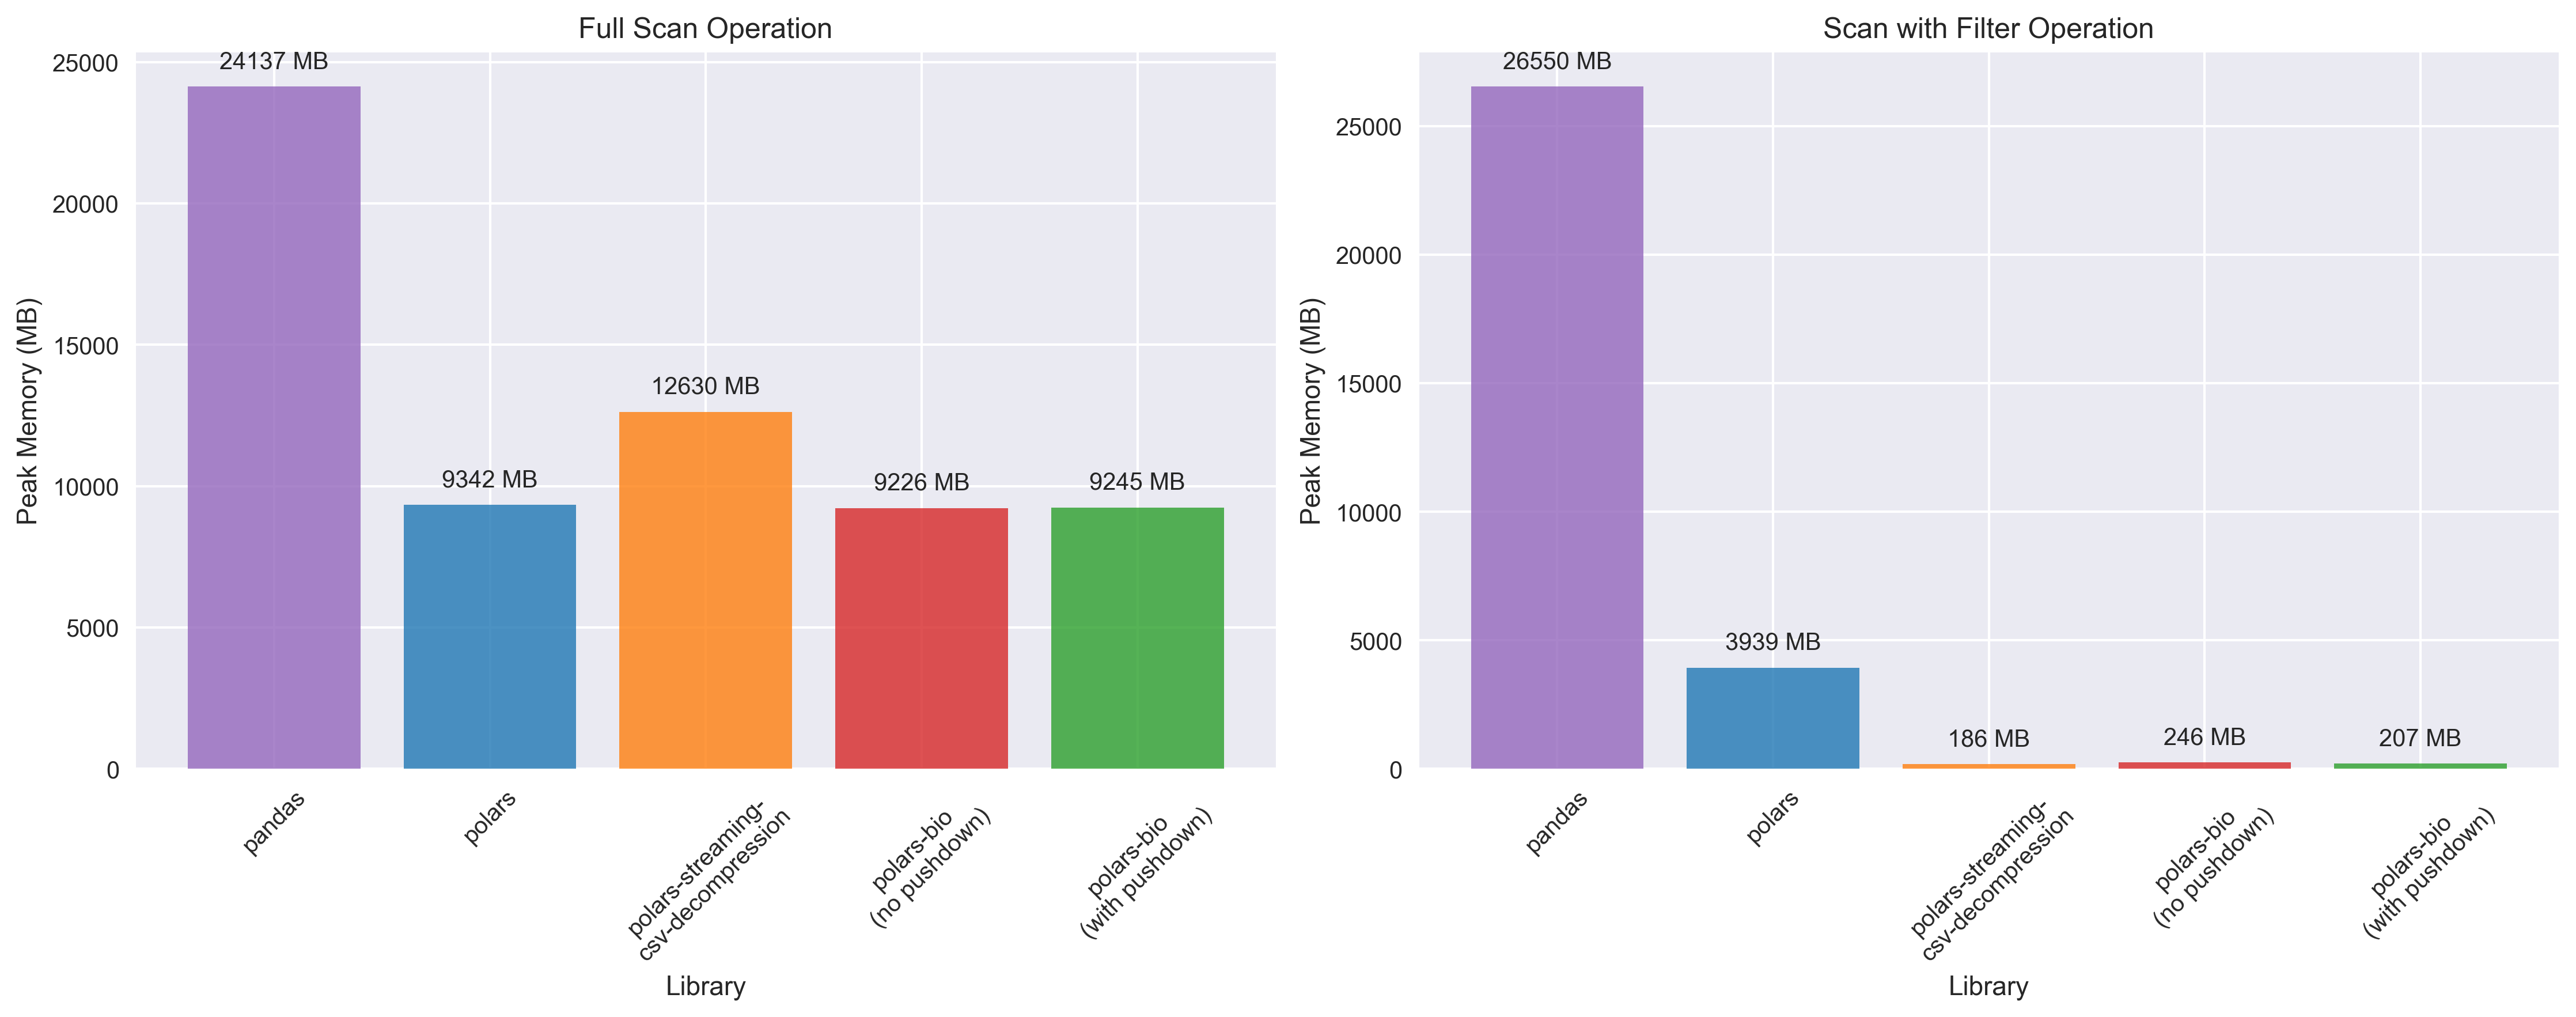
Memory usage

memory_comparison.png

Key takeaways:

  • Polars and polars-bio use significantly less memory than Pandas for all operations.
  • polars-bio and Polars with polars_streaming_csv_decompression can use more than 20x less memory than vanilla Polars and more than two orders of magnitude less memory than Pandas for operations involving filtering.
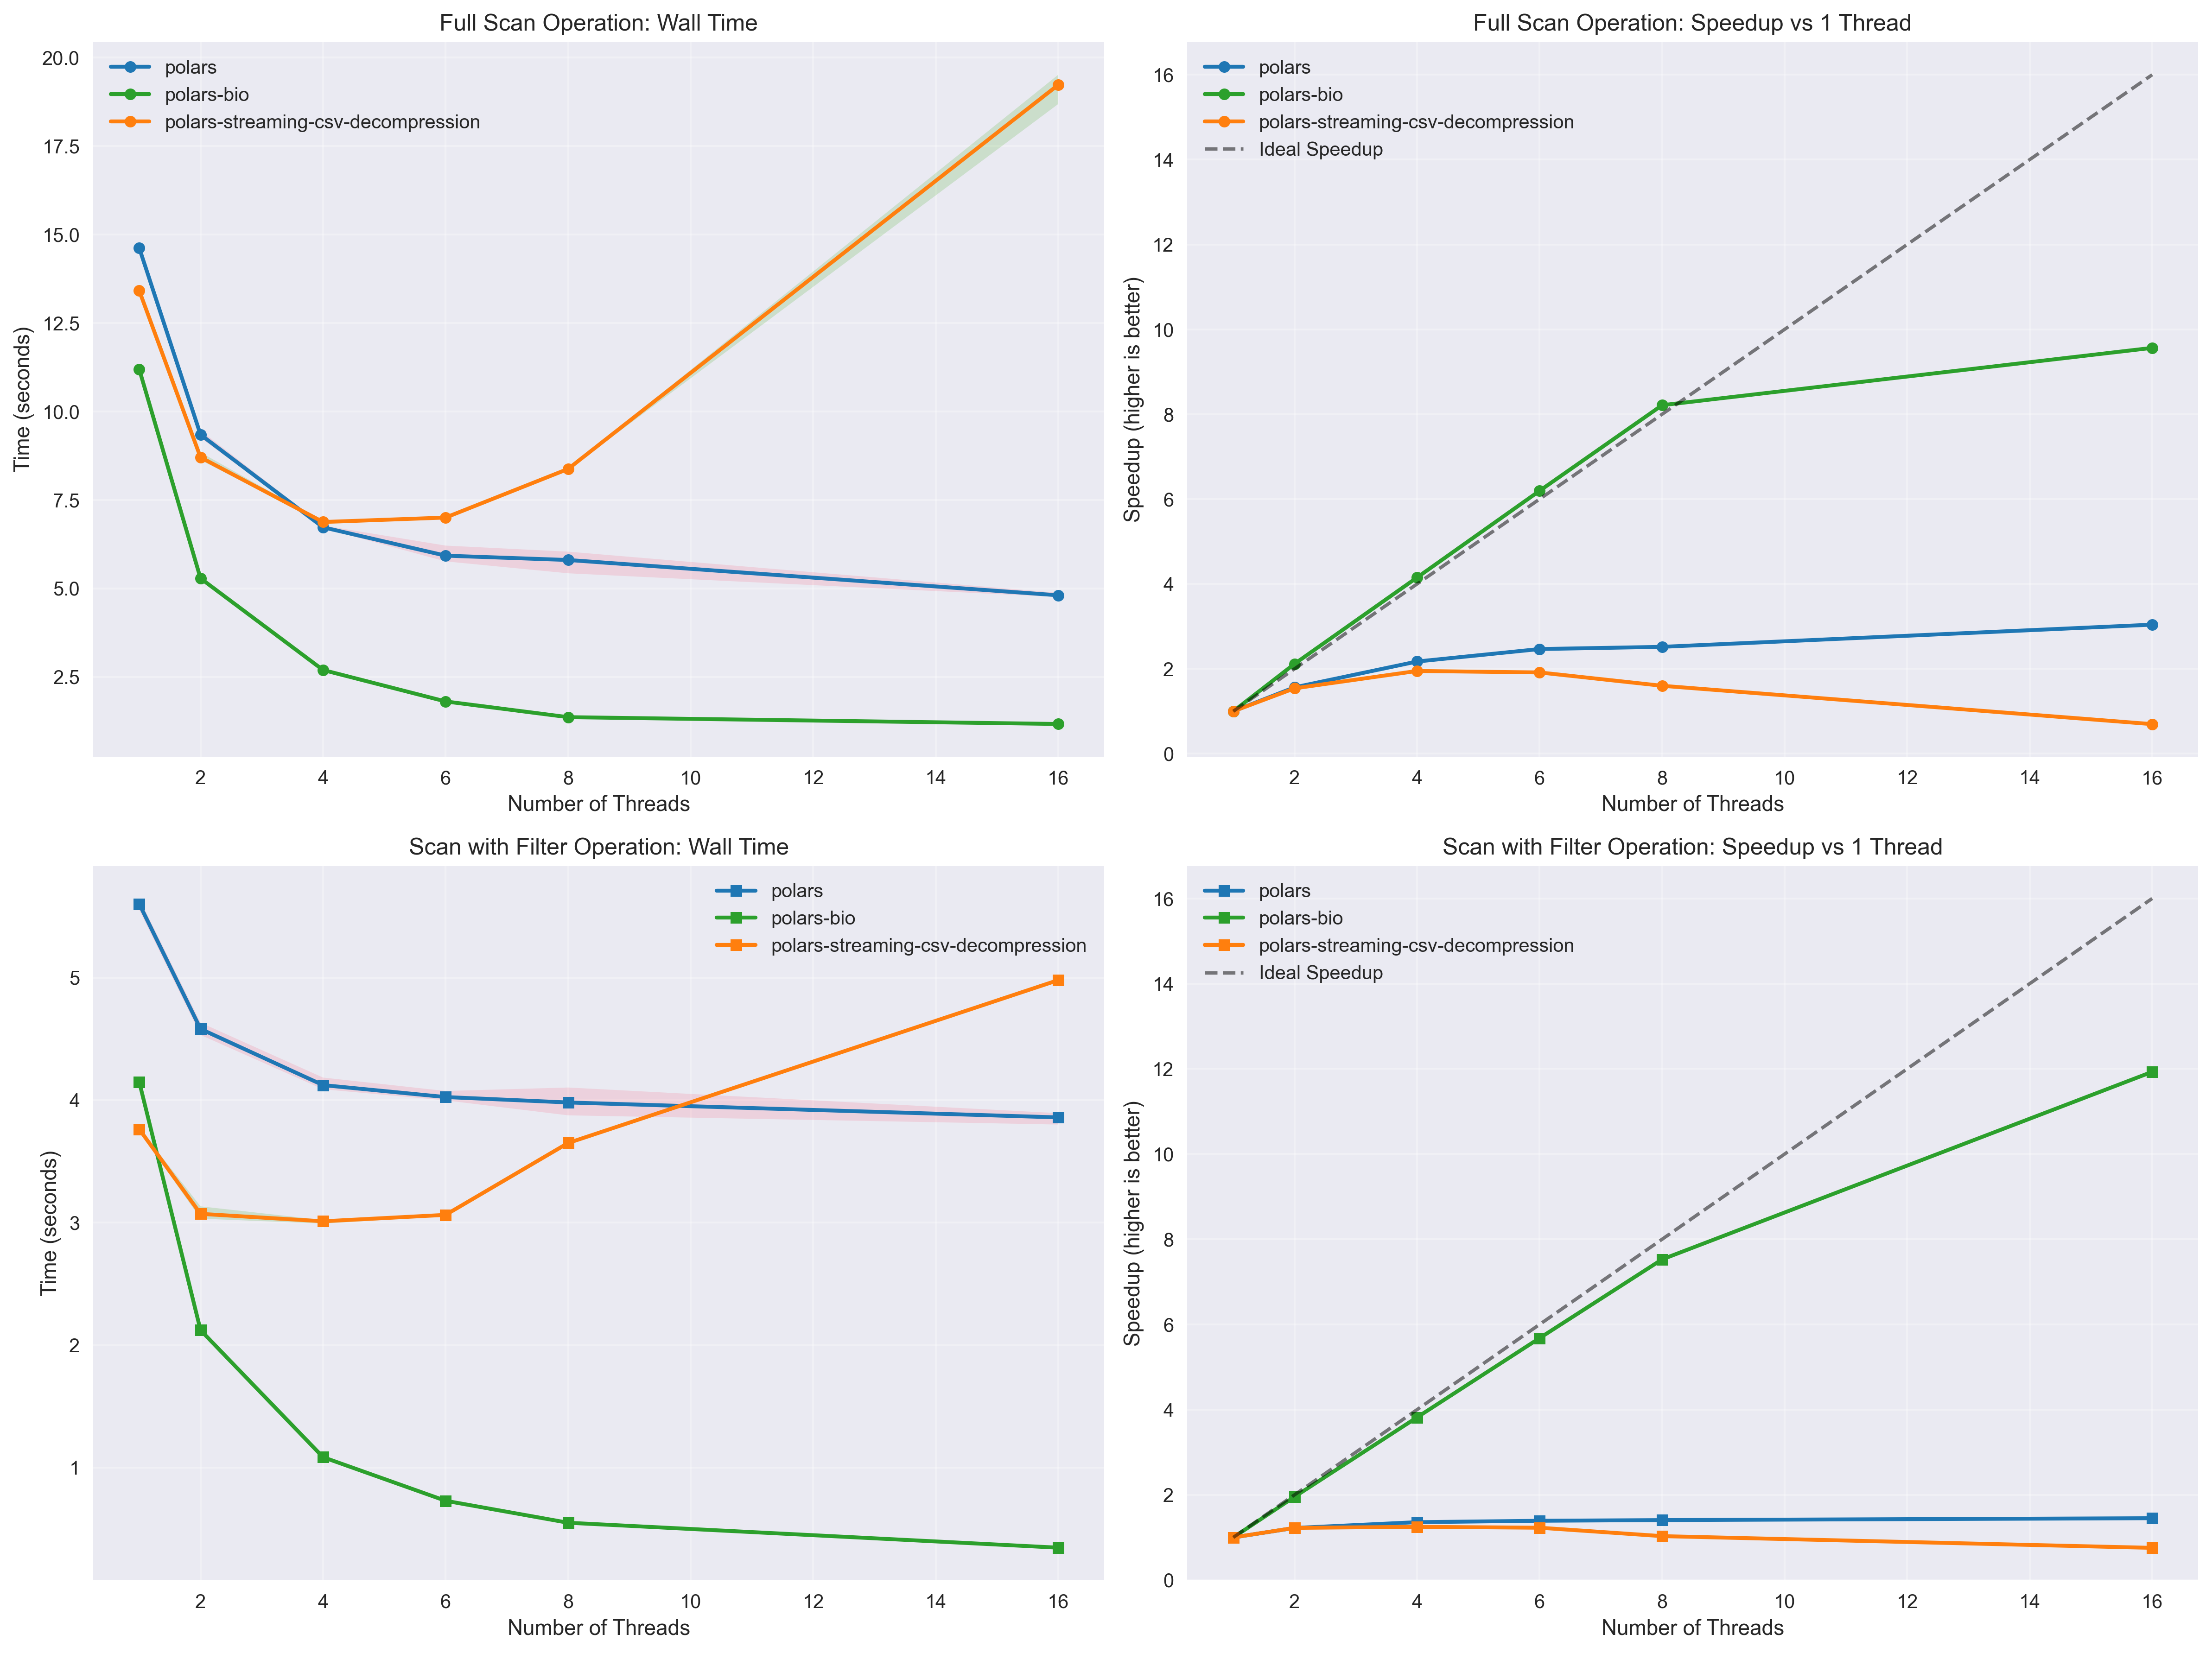
Thread scalability

thread_scalability.png

Key takeaways:

  • polars-bio achieves near-linear scaling up to 8 threads for full scan operations, reaching 9.5x speedup at 16 threads compared to single-threaded performance.
  • Filtered operations show excellent parallelization with polars-bio reaching 11x speedup at 16 threads, significantly outperforming other libraries. There is, however, non-negligible overhead due to parallelism at 1 thread (2.25s vs 4.2s, compared to the single-threaded benchmark).
  • polars-streaming shows diminishing returns at higher thread counts due to the overhead of spawning decompression program threads (in the default configuration, this is capped at 4), while polars-bio maintains consistent scaling benefits.

Summary

The benchmarks demonstrate that polars-bio 0.15.0 delivers significant performance improvements for GFF file processing. These optimizations, combined with near-linear thread scaling and fully streamed parallel reads, make polars-bio an ideal choice for high-performance genomic data analysis workflows.

If you haven't tried polars-bio yet, now is a great time to explore its capabilities for efficient genomic data processing with Python! Join our upcoming seminar on September 15, 2025, to learn more about polars-bio and its applications in genomics. seminar.png